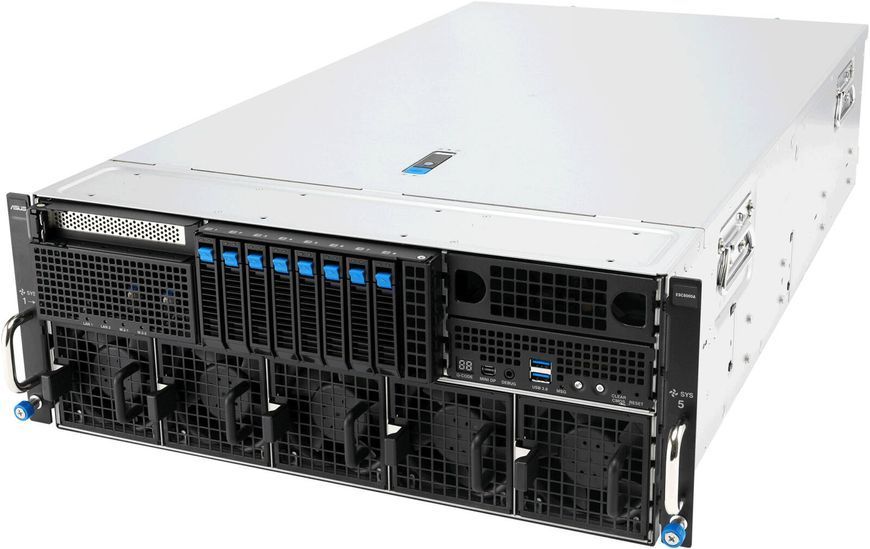
A server for production inference, where one machine hosts several models and each needs its own memory. Four NVIDIA RTX PRO 6000 Blackwell Server Edition cards give 384 GB of VRAM. Per gigabyte that is the best value among server GPUs.
Configuration
- Platform: 4U rack chassis, up to 8 GPUs
- CPUs: 2× AMD EPYC 9355
- Memory: 768 GB DDR5-6400 ECC Registered (12× 64 GB)
- GPUs: 4× NVIDIA RTX PRO 6000 Blackwell Server Edition 96 GB
- Storage: 2× 960 GB M.2 for the OS in RAID1, 2× 7.68 TB U.2 NVMe for data
- Networking: 2× 25GbE, 200G optional
- Power: 4× 3200 W with 2+2 redundancy
Room to grow
The chassis holds eight cards, which is 768 GB of GPU memory, and system memory scales to 1.5 TB. Cards are shared between teams through MIG: each team gets an isolated slice of a GPU instead of queuing for a whole one.
How to order
Card count, memory and storage are chosen for the workload. A manager quotes the price and lead time, just send a request.
Common questions
Why four RTX PRO 6000 instead of two H200?
Four 96 GB cards give 384 GB of GPU memory and four independent devices for different models or teams. H200 NVL wins when a single model must sit in one shared memory pool.
Can the cards be shared between teams?
Yes. The RTX PRO 6000 Server Edition supports MIG, so a card splits into isolated slices with their own memory. That is the standard way to share one machine.
How much dataset storage is there?
Two 7.68 TB U.2 NVMe drives for data plus two 960 GB M.2 system drives in RAID1. Capacity is extended to fit your datasets.
Do I need an NVIDIA AI Enterprise licence?
Not necessarily. The subscription for the RTX PRO 6000 Server Edition is listed separately for three or five years and matters when you want vendor support.
Can the build be changed?
Yes. Card count, memory, drives and networking are matched to the load. Describe the task on the custom configuration page.
What is the lead time?
The system is built to order. A manager confirms the exact lead time for your configuration on request.