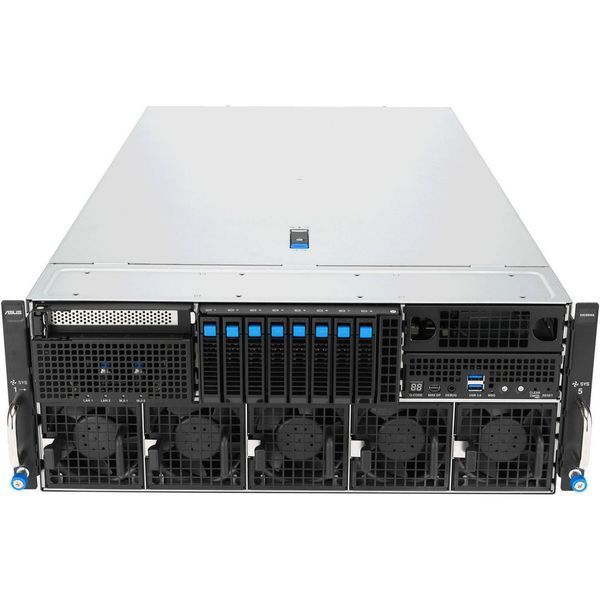
A machine for model training and heavy inference, where GPU memory decides everything. Two NVIDIA H200 NVL cards of 141 GB each are joined by an NVLink bridge, so a workload sees 282 GB as one pool and card-to-card traffic bypasses PCIe.
Configuration
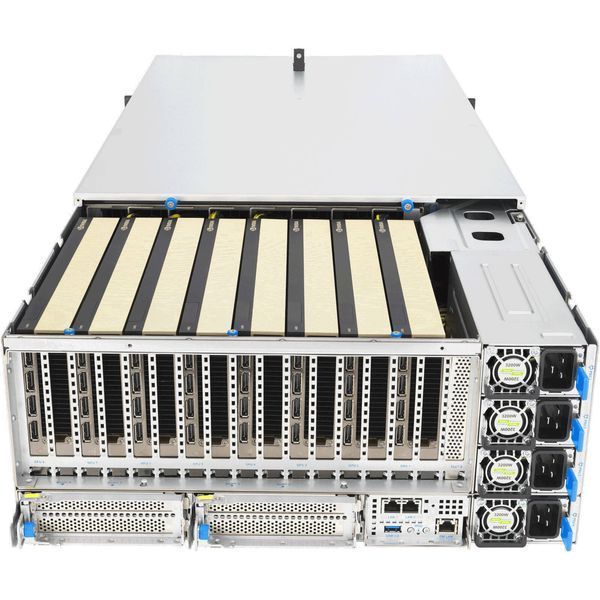
- Platform: 4U rack chassis, up to 8 GPUs, PCIe 5.0
- CPUs: 2× AMD EPYC 9355, 64 cores in total
- Memory: 1 TB DDR5-6400 ECC Registered (16× 64 GB)
- GPUs: 2× NVIDIA H200 NVL 141 GB with an NVLink bridge
- Storage: 2× 960 GB NVMe M.2 for the OS in RAID1, 4× 7.68 TB U.2 NVMe for data
- Networking: 2× 25GbE plus a dual-port 200G QSFP112 adapter
- Power: 4× 3200 W with 2+2 redundancy
Room to grow
The board takes up to four H200 NVL cards with a 4-way bridge, and memory scales to 2 TB. An NVIDIA AI Enterprise subscription is supplied separately.
How to order
Each system is built for the workload: card count, memory and storage are agreed before the order. A manager quotes the price for your configuration and the lead time. Send a request and we will calculate it.
Common questions
How many GPUs can it hold?
Two H200 NVL cards with an NVLink bridge in the base build, 282 GB of GPU memory together. The 4U platform holds up to eight cards, and a 4-way bridge pools four H200 NVL.
How much system memory, and can it grow?
1 TB of DDR5-6400 ECC Registered across sixteen 64 GB modules. It scales to 2 TB with 128 GB modules.
What power does the rack need?
Four 3200 W units in a 2+2 redundant layout. The rack must carry the peak draw of two 600 W cards plus the CPUs, so we size the power with headroom together with you.
Do I need an NVIDIA AI Enterprise licence?
Not to run the system. The licence matters when you want vendor support for the inference stack and GPU virtualisation. It is supplied separately and picked to fit the workload.
Can the build be changed?
Yes. Drives, memory, the network card and the GPU count are adjusted to the workload. Describe it on the custom configuration page and we will quote a specification.
What is the lead time?
The system is built to order. A manager confirms the exact lead time for your configuration on request.